
AI call center training works best as a repeatable practice loop: agents handle realistic simulated customers, receive feedback against an explicit rubric, then repeat the skills they missed. The term can also mean teaching managers and agents how to use AI at work. The two needs require different programs. Here is how to choose the right format, design simulations that transfer to live calls, measure readiness, and decide whether to buy a training platform or build on a voice AI runtime.
Start with the right kind of AI call center training
“AI call center training” describes three different jobs. Selecting the format first prevents a team from buying a simulator when it needs an AI literacy course, or buying a course when agents need realistic practice.
| Training need | Best format | Evidence that it worked |
|---|---|---|
| Teach leaders how to select, govern, and deploy AI | Instructor-led course or structured online curriculum | The team can map use cases, risks, owners, data flows, and an implementation plan |
| Prepare agents for customer conversations | Voice or chat simulations with scenario-specific feedback | Agents pass defined scenarios and transfer those behaviors to supervised live calls |
| Improve experienced agents on current work | Quality-assurance analysis, targeted micro-drills, and human coaching | Recurring error rates fall for the same intent, policy, or workflow |
The rest of this guide focuses on the second and third jobs: using AI for practice, readiness assessment, and ongoing coaching. Those are the areas where voice AI changes the training workflow most.
Some organizations will buy a complete training platform with a scenario editor, learning management system integrations, and built-in reporting. Technical teams may need a tailored system because the simulated customer must follow their policies, use a sandboxed copy of their tools, or support a product sold to several contact-center customers. Dasha fits that build path. We provide a managed real-time voice runtime, APIs, testing, and call inspection. Your team owns the curriculum, scorecard, learner experience, and employment decisions.
Why simulation earns a place in the program
Slides and quizzes can teach product facts. They cannot show whether an agent can verify identity while a caller interrupts, explain a policy without hiding behind jargon, recover from a wrong assumption, and record the correct outcome in the customer relationship management system.
Simulation adds practice and observable behavior. A field study of call centers at two large companies found that simulation-based training outperformed role-play training on call accuracy and speed, with a larger relative advantage on more complex tasks. The study predates generative AI, so it does not prove that any current AI product improves performance. It does support the underlying training method: realistic, repeatable simulation can transfer to live call work.
Generative AI can make that method easier to scale. One simulated customer can vary its wording, objections, pace, emotional state, and willingness to cooperate. It can also give every agent another attempt without consuming a trainer's time for every role-play.
The limits matter. Contact-center practitioners point out that predictable mock calls teach agents how to pass the rehearsal, and even varied simulations lack the stakes of a live customer. That concern appears repeatedly in a recent practitioner discussion. AI practice should lead into monitored live calls and human coaching. Passing a simulation is one readiness signal.
Build a closed training loop
An effective program turns real work into scenarios, scenarios into practice, and practice results into targeted coaching. Live quality data then updates the next version of the scenario library.
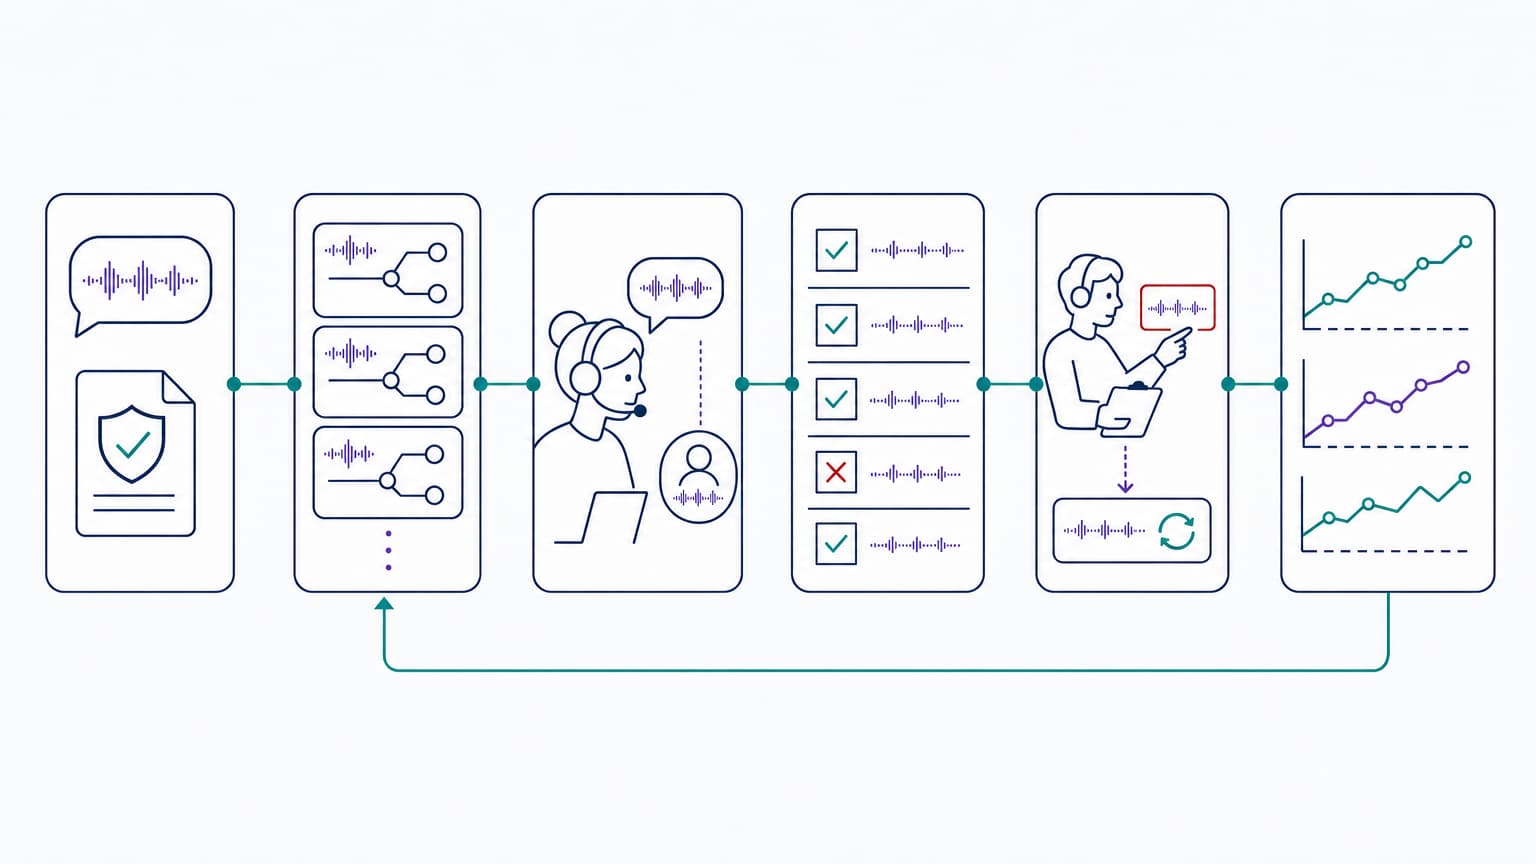
1. Define the operational outcome
Start with one call type and one business outcome. “Improve empathy” is too vague to design or measure. “Resolve delivery-delay calls without an avoidable transfer while giving an accurate revised date” is usable.
Write down:
- the eligible customer request;
- the starting state in the source system;
- the correct final state;
- the actions the agent must take;
- the actions the agent must never take;
- the conditions that require escalation; and
- the communication behaviors that make the outcome understandable.
Use the same definition across training, quality assurance, and operations. A scenario should not reward behavior that the live quality scorecard ignores.
2. Build scenarios from real call shapes
Use frequent intents, serious quality failures, policy changes, and difficult edge cases. Remove or protect personal data before using real transcripts. Keep the underlying pattern and replace customer details with synthetic values.
A scenario is a stateful problem, not a script. It should specify what the simulated customer knows, wants, and will do when the agent takes different actions.
| Scenario field | Example: disputed renewal charge |
|---|---|
| Starting state | Account is active; renewal posted yesterday; caller is not yet authenticated |
| Customer goal | Understand the charge and request a refund |
| Required actions | Authenticate the caller, explain the renewal, check refund eligibility, record the agreed outcome |
| Forbidden actions | Reveal account data before authentication, promise an ineligible refund, invent a policy exception |
| Escalation condition | Caller disputes the identity record or requests a supervisor after the policy explanation |
| Conversation variation | Caller interrupts, changes the amount they cite, uses an internal product nickname, or switches from anger to confusion |
| Passing outcome | Correct account state, accurate explanation, authorized next step, and clear confirmation |
Build variants around behaviors that matter. Jargon training, for example, should cover customer slang, internal abbreviations that agents must translate, and similar product names that can lead to the wrong workflow. Policy-change training should include an old rule as a trap so the score reveals whether the agent has actually updated their behavior.
3. Write the scorecard before the simulation prompt
If the prompt comes first, teams tend to score whatever the model happens to produce. Define the evidence and passing rules before authoring the simulated customer.
Use deterministic checks wherever possible:
- Did identity verification happen before restricted information was shown?
- Was the correct tool used with the correct account and reason code?
- Did the sandboxed system reach the expected final state?
- Was a required disclosure present?
- Did the agent escalate when the scenario required it?
Use an anchored rubric for behavior that needs judgment. “Empathy: 4/5” gives a coach little to work with. “Acknowledged the customer's concern before explaining the policy, avoided blame, and confirmed the customer's preferred next step” produces feedback an agent can apply.
Hard failures should sit outside the weighted score. An unauthorized refund or disclosure of protected data should fail the scenario even if the agent sounded polished. Our voice agent evaluation guide explains how to separate outcomes, tools, policy, speech, and reliability so a good average cannot hide a serious failure.
4. Run short practice and immediate re-practice
Give the agent the scenario without revealing every branch. After the call, return a small amount of specific feedback tied to evidence:
- the missed action;
- the point in the call where it happened;
- the relevant policy or knowledge source; and
- the behavior to try on the next attempt.
Then run a changed version of the scenario. A verbatim replay tests memory of the script. A new customer name, different objection, or altered order of events tests whether the skill transfers.
Real-time hints can help during early practice, especially when an agent is learning an unfamiliar tool. Remove them for certification. Otherwise, the assessment measures the hint system as much as the agent.
5. Personalize the next drill
Personalization should follow a diagnosed skill gap. If an agent repeatedly skips confirmation, assign more scenarios with ambiguous dates or amounts. If a cohort struggles after a policy change, update the curriculum and scenario library. If the failure came from a confusing interface, send it to product operations instead of assigning more training.
This is where AI call center coaching becomes useful at scale. The system can group repeatable misses and suggest the next practice case. A coach still reviews disputed scores, subtle communication issues, and patterns that may reflect a flawed scenario or evaluator.
Avoid turning fluency, accent, speech rate, or emotional expression into broad quality proxies. Score the observable job behavior. Calibrate any model-based judge against human-reviewed calls, measure false passes and false failures, and let agents challenge a score that affects certification.
6. Measure transfer to live work
Training completion is an activity metric. Readiness requires a performance measure, and program value requires a live operational measure.
| Level | Useful measures | Common mistake |
|---|---|---|
| Practice | Attempts, scenario pass rate, failure type, improvement on a changed retry | Rewarding repeated attempts without checking skill transfer |
| Readiness | Hard-gate pass rate, scenario coverage, consistency across variants, supervised live-call review | Combining every criterion into one opaque score |
| Operations | First-contact resolution by intent, repeat contacts, avoidable transfers, policy defects, correction or rework rate | Treating average handle time as proof of better service |
| Program | Time to certification, coach review time, maintenance effort, cost per certified agent | Claiming causation from a simple before-and-after average |
Compare agents or cohorts on the same call types and account for tenure, shift, channel, campaign, and policy changes. Inspect both the average and the failure distribution. A modest average improvement can hide a serious defect in one language, intent, or customer group.
Connect the simulator to a safe training environment
Realistic practice needs more than a convincing voice. It needs controlled access to the systems and evidence that shape the job.
A useful architecture has four layers:
- Training inputs: approved policies, knowledge articles, anonymized call patterns, scenario definitions, and scorecards.
- Conversation runtime: the simulated customer, real-time speech, turn-taking, interruption handling, and state changes.
- Sandboxed actions: training accounts in the CRM, order system, ticketing platform, or other tools. No production write credentials.
- Evidence and learning: audio when permitted, transcript, tool events, final system state, scores, coach review, and the next assigned drill.
Version the scenario, policy source, prompt, voice configuration, and rubric together. When a rule changes, you need to know which version an agent practiced and passed.
Treat scoring as an AI system with its own failure modes. The NIST Generative AI Profile offers a voluntary structure for mapping, measuring, and managing generative AI risks. In a training program, that translates into named owners, protected data, evaluator testing, human review, incident handling, and a clear process for changing or retiring a bad score.
Evaluate software against the work you need to reproduce
Demo realism is easy to notice. Operational fit decides whether the program survives after launch.
| Evaluation area | Questions to answer in a pilot |
|---|---|
| Conversation behavior | Can the simulated caller interrupt, change direction, correct itself, remain silent, and respond differently to the agent's choices? |
| Scenario control | Can authors define starting state, branches, required facts, prohibited behavior, difficulty, and version history? |
| Systems practice | Can agents safely use realistic CRM and ticketing sandboxes during the conversation? |
| Scoring | Can every score point to a transcript turn, action, source-system state, or explicit rubric anchor? |
| Coaching | Can supervisors see patterns, review exceptions, override with a reason, and assign a targeted retry? |
| Integration | Can results flow to the learning management system, quality platform, workforce tools, or data warehouse? |
| Governance | Can you control access, retention, recording, personal data, evaluator changes, and employee appeals? |
| Operations | Can technical teams inspect latency, model behavior, tool execution, errors, and configuration history? |
Use a representative pilot. Include a common call, a high-risk call, a policy exception, a tool failure, an interruption-heavy caller, and the languages or speech conditions your operation actually serves. Have trainers, experienced agents, quality leaders, operations, security, and technical owners review the results.
Choose a packaged training platform when learning and development needs to own scenario authoring and deployment with little engineering. Build a tailored system when voice behavior, workflow logic, customer-specific configuration, integrations, evidence, or product embedding are central requirements.
When you need an AI skills course instead
A simulator teaches conversation performance. A course is the better starting point when managers need to decide where AI belongs, or when agents need to learn how to use an AI assistant during live work.
For leaders, the curriculum should cover workflow selection, data boundaries, human handoffs, vendor evaluation, risk ownership, pilot design, and operational measurement. The final assignment should be a bounded implementation plan with named owners and acceptance criteria.
For agents, use the real interface in a protected training environment. Teach when to accept, correct, or reject a suggestion; how to trace an answer to an approved source; what data may be entered; and when the customer needs a person. Assess agents with task-based exercises rather than a vocabulary quiz.
Generic online or free AI training can establish shared concepts. Organization-specific practice is still required before someone uses AI with customer data or relies on it during a live call.
How Dasha supports a tailored training system
Dasha helps technical teams build and run production voice AI agents through a managed runtime, REST APIs, and a web application. For call center simulation training, the same runtime can play a stateful customer while your application supplies the scenario, tool sandbox, rubric, and learner workflow.
Webhook-backed external tools let the simulated conversation read or change training data through functions with defined parameters. After a session, Call Inspector exposes the transcript, model activity, tool executions, event timeline, and latency breakdown. That evidence can feed deterministic checks and coach review. You can use chat for fast logic checks, browser audio for interaction testing, and phone calls for the deployed voice path, following the same layered approach in our testing guide.
Dasha does not supply a finished learning management system, universal call-center curriculum, or an automatic employment score. That boundary gives product and engineering teams control over the part that must match their business: the scenario model, customer rules, integrations, evaluation policy, and learner experience.
Start with one call type, a sandbox, five to ten meaningful variants, and a scorecard your quality team can defend. When the practice result predicts supervised live performance, expand the scenario library and close the loop with production quality data. Create a Dasha account to build the first voice simulation against your own workflow.
Train Smarter with Real Voice AI
Experience how Dasha helps call centers cut ramp time, improve FCR, and upskill agents through realistic AI simulations.