
Generative AI earns its place in insurance when it handles language work around a regulated decision: extracting a submission, summarizing a claim file, explaining approved policy language, or capturing first notice of loss. It should not invent coverage, set a premium, deny a claim, or approve a payout. A sound implementation separates generated content from rules, predictive models, systems of record, and accountable human judgment.
What generative AI means in insurance
Generative AI creates or transforms content such as text, speech, images, summaries, and structured records. A large language model can turn a long submission into an underwriter brief, convert a phone conversation into first-notice-of-loss fields, or draft a customer response from approved policy material.
That is different from the AI insurers already use for prediction and classification. A fraud model produces a risk score. A pricing model estimates an outcome. A rules engine applies an explicit eligibility or routing policy. A generative model produces an answer, explanation, summary, or proposed action. Production workflows often use all four, with distinct responsibilities.
| System | Best at | Example insurance output | Decision boundary |
|---|---|---|---|
| Rules engine | Applying explicit policy | Route a claim above a defined threshold | Business owners approve and version the rules |
| Predictive model | Estimating or classifying | Fraud risk score or expected loss | Validated model supports an authorized decision process |
| Generative model | Reading and producing unstructured content | Claim summary, policy explanation, draft correspondence | Output is evidence or a draft, unless a separate control authorizes more |
| AI agent | Orchestrating a multi-step task with tools | Retrieve claim status, create a service case, and confirm receipt | Each read and write is authenticated, scoped, and logged outside the model |
The practical dividing line is simple: use generative AI for interpretation and communication. Keep coverage, eligibility, pricing, reserving, liability, fraud disposition, and payment authority in governed systems and accountable roles.
For the wider role of prediction, automation, and machine learning, see our guide to AI for insurance. Product and offer tailoring is a separate topic covered in personalized insurance.
Choose insurance use cases by decision distance
Decision distance is the number of controlled steps between a generated output and an outcome that affects a customer. An internal summary reviewed by an adjuster has more distance than an automated coverage answer sent directly to a policyholder. Greater distance usually makes a better first pilot.
| Use case | Generative AI's job | Required boundary | Useful pilot measure |
|---|---|---|---|
| Submission intake | Extract fields, compare documents, summarize missing information | Underwriter confirms material facts and requests | Field accuracy, omission rate, review time |
| Underwriting assistant | Retrieve guidelines, draft a risk narrative, surface conflicting evidence | Rating, eligibility, and terms stay with approved models, rules, and underwriters | Source support, edit rate, turnaround time |
| First notice of loss | Conduct intake, structure the account, and summarize attachments or calls | No decision on coverage, fault, severity, reserve, or payment | Required-field completion, correction rate, handoff completeness |
| Claim file review | Build a timeline and summarize notes, estimates, images, and correspondence | Adjuster owns investigation, coverage interpretation, and disposition | Missed-fact rate, unsupported statement rate, review time |
| Policy service | Explain approved language, retrieve status, and open a service request | Live facts come from policy and billing systems; exceptions transfer to staff | Correct resolution, stale-answer rate, repeat contact |
| Agent and broker support | Search product material, compare approved options, and draft follow-up | Licensed professionals own suitability, advice, and final communication | Retrieval precision, editing time, compliance corrections |
| Fraud investigation support | Organize evidence, link related records, and draft an investigation brief | A separate process validates signals and owns any adverse action | Evidence recall, false assertion rate, investigator acceptance |
| Compliance and operations | Summarize regulatory changes, draft procedures, and classify complaints | Legal and compliance teams interpret obligations and approve changes | Material omissions, reviewer edits, time to approved draft |
The lower-risk end of this table starts with internal retrieval, summarization, and drafting. Customer-facing service can follow once grounding, identity, escalation, and monitoring work. Underwriting, claims, fraud, and personalized recommendations need stronger evidence, fairness testing, and decision controls because an error can change access, price, or payment.
Where conversational and voice AI fits
Insurance work often begins in a conversation. A policyholder calls after a loss. An applicant has questions while completing a form. An agent needs a current product detail during a client meeting. Generative AI can turn those exchanges into a structured, traceable workflow.
A bounded voice agent can:
- collect first-notice-of-loss details and create an intake record;
- answer approved policy-servicing questions;
- retrieve claim, payment, or application status after the required identity check;
- schedule an appointment or create a callback request;
- place consented reminder and follow-up calls;
- transfer an exception with the caller's reason and the facts already collected; and
- produce a transcript, summary, and structured outcome for review.
We provide the managed conversational layer for technical teams building these flows. Dasha runs inbound and outbound phone agents plus browser voice and chat, calls external tools, uses connected knowledge, sends webhooks, transfers calls, and records the interaction data needed for inspection. The insurer's policy administration, claims, billing, identity, authorization, and decision systems remain authoritative.
Dasha is not an underwriting, coverage, pricing, or claims-decision product. It does not make an insurance workflow compliant by itself. Its role is to run and operate the conversation while your application enforces identity, data access, business policy, and escalation.
Outbound voice also has channel-specific obligations. The FCC has confirmed that the Telephone Consumer Protection Act's restrictions on an “artificial or prerecorded voice” cover AI-generated voices. Consent, identification, do-not-call, recording, disclosure, and retention requirements must be designed for the use case and every jurisdiction it reaches.
Build an architecture that preserves decision rights
A production insurance assistant needs more than a model and a prompt. It needs an evidence path from the customer or employee request to the final system state.
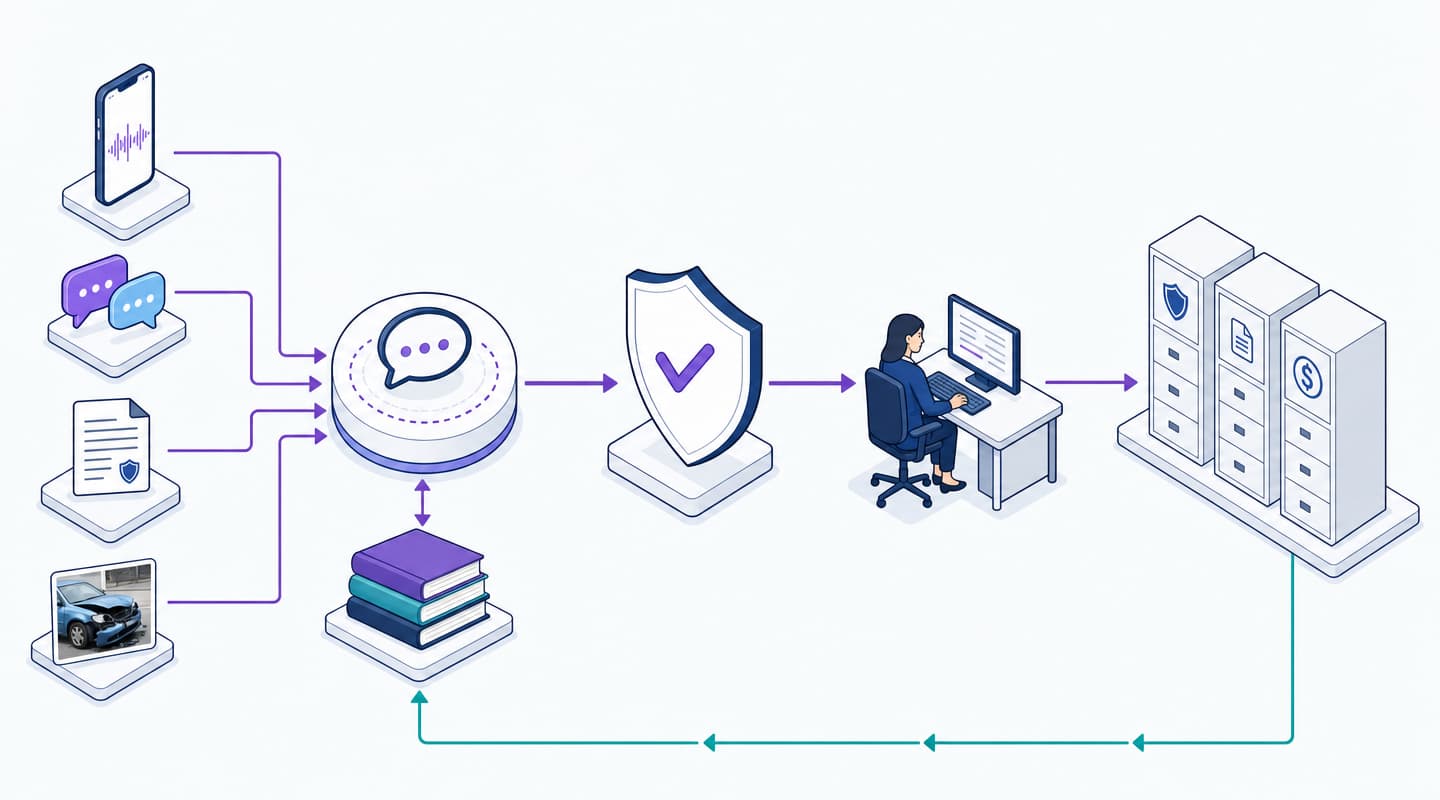
1. Separate reference content from live state
Approved policy forms, product guides, scripts, and procedures belong in a versioned knowledge store. Claim status, payment state, customer identity, limits, and open tasks belong in operational systems and should be retrieved through typed tools.
This distinction prevents a common failure. A model may correctly retrieve a policy form and still give the wrong answer for a customer whose endorsement, jurisdiction, or effective date is different. Policy language can support an explanation. Live coverage facts must come from the actual contract record and an authorized process.
2. Put policy enforcement outside the model
Treat every model-generated tool call as a proposal. A deterministic service should authenticate the principal, enforce tenant and record scope, validate arguments, apply business rules, decide whether approval is required, and return an explicit result.
Use narrow operations such as get_claim_status, create_callback_request, or submit_fnol_draft. Avoid giving the model a generic database client or broad CRM credential. Separate read tools from write tools and make mutations idempotent so retries cannot create duplicate cases or payments.
3. Create an evidence envelope for every material output
Store enough context to reconstruct what happened:
- user, customer, tenant, channel, and session identity;
- model, prompt, workflow, and knowledge-release versions;
- retrieved document IDs, versions, and passages;
- tool requests, authorization results, responses, and timestamps;
- generated answer or proposed action;
- human review, edits, override reason, and final decision; and
- final record ID and state in the system of record.
A transcript alone is insufficient. It shows what was said, while the evidence envelope shows which sources supported it, which action was authorized, and whether the downstream write succeeded.
4. Design failure behavior before the happy path
Define what happens when identity cannot be established, retrieval finds conflicting forms, an API times out, speech recognition produces an uncertain name, or no approved answer exists. The safe response may be a targeted clarification, a read-only fallback, case creation, or transfer. It should never be a plausible guess.
Control the risks specific to generative AI
The NIST generative AI profile identifies risks including confabulation, data privacy, harmful bias, information security, and over-reliance. Insurance adds regulated decisions, sensitive records, and a duty to explain many adverse outcomes.
| Risk | How it appears in insurance | Control that changes the outcome |
|---|---|---|
| Unsupported output | The assistant invents a deductible, exclusion, claim status, or next step | Retrieve approved sources, require live tools for live facts, return source IDs, and abstain when evidence is missing |
| Unfair discrimination | A summary, recommendation, or generated message treats groups differently or hides a biased upstream signal | Test by relevant groups and scenarios, examine proxy variables, constrain the role, and preserve review and appeal |
| Sensitive-data exposure | Health, financial, driving, property, or claim data enters an unapproved model, log, or support tool | Minimize fields, isolate tenants, encrypt data, redact logs, define retention, and control provider use of inputs |
| Prompt injection and tool misuse | A document, caller, email, or tool response tells the agent to reveal records or change an outcome | Treat external content as data, preselect minimum tools, authorize every action outside the model, and restrict egress |
| Automation bias | A reviewer accepts a fluent summary without checking missing or contradictory evidence | Show supporting passages and uncertainty, sample accepted outputs, and measure human correction and override |
| Version drift | A model, prompt, policy form, or retrieval index changes behavior silently | Version every component, run regression gates, use staged rollout, and keep a tested rollback path |
| Voice error | A name, date, amount, or address is misheard during a call | Read back material fields, request confirmation, retain the audio-to-field trace, and transfer unresolved ambiguity |
Accuracy should be measured at the task level. A polished answer can contain one material error. A high-quality claim intake captures every required fact, marks uncertainty, creates one valid record, and sends a complete handoff. Those are separate assertions in a test.
Insurance AI regulation makes governance an operating requirement
Existing insurance law still applies when an AI system supports the work. The model does not absorb the insurer's accountability, and a vendor's proprietary system does not remove the need for evidence.
The NAIC's AI model bulletin expects insurers adopting it to maintain a written, risk-proportionate AI systems program. It covers governance, data practices, validation, testing, human involvement, explainability, third-party oversight, records, and the full system lifecycle. An NAIC adoption map dated August 31, 2026 lists 26 adopting jurisdictions and four more with insurance-specific regulation or guidance.
New York's Circular Letter No. 7 is narrower and more detailed for underwriting and pricing. It makes the insurer responsible for third-party systems, calls for pre-production and recurring discrimination analysis, expects an inventory and lifecycle documentation, and requires meaningful information about data and reasons behind adverse underwriting or pricing outcomes.
In the European Union, life and health insurance AI used for risk assessment and pricing can fall into the AI Act's high-risk category. EIOPA's insurance AI opinion explains how existing sector rules apply to other insurance AI systems through a proportionate framework covering fairness, data governance, records, explainability, human oversight, accuracy, resilience, and cybersecurity.
The operational lesson is consistent across these regimes. Maintain an inventory by use case, map the consumer impact and applicable rules, document who owns the decision, test before release and after material changes, retain evidence, supervise vendors, and provide a working complaint and redress path.
Run a controlled generative AI pilot
1. Pick one bounded task and baseline
Choose a repetitive task with stable inputs, a visible reviewer, and a measurable outcome. Claim-file summarization or internal product retrieval is usually a safer first pilot than automated policy recommendations. Record the current review time, error types, rework, queue age, and escalation rate.
2. Write the decision-rights contract
List what the system may read, generate, recommend, write, and never do. Name the owner of every exception. Define identity requirements, data fields, source hierarchy, approval points, transfer reasons, and stop conditions.
3. Build the data and tool contracts
Clean and version the approved source set. Implement read-only tools first. Return structured not_found, conflict, and unavailable states. Add minimum-scope write tools only after authentication, authorization, retries, and audit events are proven.
4. Create a representative evaluation set
Use real workflow shapes with appropriately protected or synthetic data. Include common cases, rare endorsements, conflicting documents, missing fields, older policy versions, multiple jurisdictions, long histories, poor audio, accented speech, interruptions, adversarial instructions, and upstream outages.
Score each requirement independently:
- material fact extraction and omission;
- answer support and source selection;
- required disclosure and prohibited claims;
- tool selection, argument validity, and write success;
- identity, authorization, and cross-customer isolation;
- performance across relevant languages, groups, and channels;
- handoff reason and summary accuracy; and
- latency, reviewer time, and cost per correctly completed task.
Any unauthorized disclosure or action, untraceable customer-impacting output, or generated coverage, price, or claim decision outside the contract should block release.
5. Shadow, assist, then automate narrowly
Start by generating outputs without exposing them to customers or changing records. Compare them with the real outcome. Move to employee-assist mode, then expose the workflow to a limited population with staffed fallback. Expand automation only where the evidence shows stable performance and the decision-rights contract permits it.
6. Turn failures into regression tests
Review a sample of successes as well as every serious failure. Tag the cause: source, retrieval, model, prompt, tool, policy, speech, integration, or human handoff. Add reproduced failures to a fixed regression suite before changing models or expanding the workflow. Our voice agent testing guide provides a full test surface for phone and web conversations.
Decide what to build and what to buy
The choice should follow the workflow layer your team wants to own.
| Option | Best fit | Your team still owns |
|---|---|---|
| Dasha managed conversational platform | Technical teams adding production phone or web conversations with tools, knowledge, transfer, testing, and monitoring | Insurance policy, data access, identity, authorizations, regulated decisions, and application-specific evaluation |
| Insurance workflow application | A packaged underwriting, claims, agent, or service process with established system connectors | Vendor oversight, configuration, data quality, decision accountability, and gaps outside the packaged workflow |
| Enterprise AI workspace | Internal search, summarization, and drafting across many functions | Insurance-specific retrieval, approvals, operational integrations, output review, and records |
| Model API or open-source stack | Teams that need direct control of models, hosting, and every orchestration component | Retrieval, tools, telephony, security, evaluation, observability, deployment, scaling, and incident response |
| Custom model development | A differentiated task with proprietary data and enough evidence that general models cannot meet it | Training data rights and quality, model risk, infrastructure, validation, governance, and ongoing maintenance |
For a conversational use case, start with one workflow that has an explicit source of truth and human fallback. Evaluate Dasha against its real tool calls, transfers, failure cases, and release gates.