
AI lead qualification fails when teams ask a model to decide who deserves sales attention without defining the evidence or the next action. A dependable system collects missing facts, preserves uncertainty, applies versioned rules, and routes each lead to a permitted outcome. The goal is faster coverage and consistent decisions without forcing buyers through a bad conversation or treating a model-generated score as unquestioned truth.
What AI lead qualification is
AI lead qualification uses machine learning, generative AI, or conversational agents to assess whether a prospective customer fits your offer, shows real buying intent, and is ready for a specific next step.
The output should be a decision record that sales can use. It needs evidence, a reason code, an action, an owner, and the version of the policy that produced the decision. A score on its own cannot explain whether a lead is a poor fit, early in the buying process, unreachable, or missing one answer.
AI can support four parts of the workflow:
| Layer | Useful role for AI | Control that stays deterministic | Output |
|---|---|---|---|
| Evidence collection | Research an account, interpret a reply, or ask a follow-up question | Approved sources, contact permissions, and question boundaries | Raw facts and conversation evidence |
| Normalization | Map free-form language to typed fields | Allowed values, validation, and rules for unknown data | Structured qualification fields |
| Decision support | Identify patterns or estimate propensity | Hard exclusions, thresholds, and permitted actions | Fit, intent, and confidence signals |
| Execution | Summarize context and select an approved next step | Ownership, routing, booking, suppression, and write permissions | CRM update, meeting, transfer, nurture, or closure |
We build Dasha for the part that happens in a live phone conversation. Our managed voice AI platform can run inbound or outbound qualification calls, use CRM and calendar tools, transfer qualified conversations, and return structured call results. If your need stops at enriching form fills or ranking a CRM list, a data or CRM scoring product is the more direct choice. If you need phone-based qualification as part of a revenue workflow or conversational AI product, our voice AI backend covers the real-time runtime and operating layer.
AI lead scoring is only one part of qualification
Lead scoring ranks or prioritizes leads. Lead qualification decides what the evidence means and what should happen next.
Three mechanisms often get bundled under the same label:
- Predictive scoring estimates an outcome such as opportunity creation from historical patterns. It is useful when you have enough clean, representative data and a stable target event.
- Rules-based qualification applies explicit criteria such as supported geography, minimum volume, account ownership, or required consent. These rules are inspectable and should control hard gates.
- Conversational qualification asks for evidence that the database does not contain, such as the buyer's goal, current process, timing, or willingness to take a next step.
A dependable system combines them. Predictive models can prioritize review. Rules can protect policy boundaries. A conversation can resolve missing or conflicting information.
| Situation | Best starting point | Main limitation |
|---|---|---|
| Thousands of CRM records with known attributes | Predictive scoring inside the CRM or data stack | Historical data may encode old sales choices and coverage gaps |
| Missing firmographic or account data | Enrichment and classification workflow | Provider data can be stale, incomplete, or wrong |
| An active website visitor with two or three open questions | Chat or messaging agent | The buyer may leave before the flow is complete |
| A requested call where clarification or transfer matters | Voice AI agent | Trust, latency, consent, and handoff quality are immediately visible |
| High-value, sensitive, or unusual request | Human-led qualification with AI assistance | Coverage depends on staff availability |
Our inbound qualification workflow goes deeper on defining fit, intent, questions, and routing for incoming demand. The AI layer should automate that policy rather than invent it.
Design the decision before the model
Start with the terminal outcomes. A practical first version may use:
- sales_now: evidence meets the sales-ready standard
- human_review: fit looks promising, but evidence is incomplete or conflicting
- nurture: the account fits and timing is early
- disqualify: a verified fact fails a serviceable-market rule
- unreachable: no qualification conversation happened
- suppressed: contact is prohibited or the person opted out
These states separate commercial judgment from operational status. Unreachable does not mean unqualified. Unknown budget does not mean no budget. A duplicate record does not mean poor fit.
Work backward from each outcome to the minimum evidence required. Every question must affect a branch, a field, or the final action.
| Business question | Structured field | Useful values | What it changes |
|---|---|---|---|
| Can we serve this use case? | use_case_fit | supported, review, unsupported | Eligibility or specialist review |
| Is the expected scope workable? | volume_band | Defined ranges plus unknown | Segment, owner, and commercial fit |
| Is there an active project? | timeline | now, this_quarter, later, unknown | Sales now or nurture |
| How will a decision be made? | buying_path | defined, partial, unknown | Discovery depth and next participant |
| Did the buyer accept a next step? | next_step_consent | book, callback, send_info, none | Permitted follow-up action |
Frameworks such as BANT, which stands for budget, authority, need, and timing, can prompt useful discovery. They are too broad to function as a production specification. “Has budget” needs a definition, an evidence source, an unknown state, and a rule for how much that field should influence the outcome.
Keep language interpretation and business policy separate
Generative AI is useful for interpreting an answer such as “We hope to replace the current process after renewal, probably late this year.” It can map that statement to a time range, retain the exact evidence, and ask for clarification if the range matters.
The model should not decide whether that time range permits a meeting, changes territory ownership, or overrides an unsupported use case. Those are business rules. Keep them in application code or a versioned rules service.
Give each extracted field an evidence state:
- confirmed: the buyer stated or confirmed it
- system_record: it came from an approved source of record
- inferred: the model derived it from indirect language
- unknown: no reliable answer exists
- conflicting: two sources disagree
Only confirmed and approved system-record values should trigger high-impact actions by default. Inferred values can drive a follow-up question or a review task.
A useful qualification result looks like this:
{
  "lead_id": "lead_4827",
  "fit": "review",
  "readiness": "sales_ready",
  "evidence": {
    "timeline": {
      "value": "this_quarter",
      "state": "confirmed"
    },
    "volume_band": {
      "value": null,
      "state": "unknown"
    }
  },
  "reason_codes": [
    "supported_use_case",
    "active_project",
    "volume_unverified"
  ],
  "action": "human_review",
  "policy_version": "2026-09-01"
}
This format makes the result explainable. It also lets you change a threshold without erasing the basis of earlier decisions.
Choose the channel based on buyer intent and friction
The fastest channel is useful only when the buyer welcomes it. Match the response to the signal:
- CRM scoring fits background prioritization. It should not interrupt the buyer.
- Email gives the buyer time to answer and creates a written record, but clarification can stretch across several messages.
- Web chat or messaging works while the buyer is active and comfortable typing.
- Voice works when the person requested a call, several answers need clarification, or an immediate transfer has value.
- A person should lead when the request is sensitive, high-value, unusual, or requires discretion outside the policy.
The strongest speed case is an explicit, high-intent inquiry sitting unowned in a queue. An older HBR field study audited 2,241 US companies and found that 23% never responded to a test web lead. Its age makes it a poor modern benchmark, but the operating lesson remains useful: every serious inquiry needs an owner and a timed response path.
Do not insert an automated gate simply because the technology is available. A buyer who asks for a specialist may see five bot questions as delay. Let the lead request a person, schedule another time, or end the interaction without pressure.
A production workflow for AI lead qualification
A reliable implementation is an event-driven path with clear ownership at every boundary:
- Trigger: A form, inbound call, product event, reply, or approved list record starts the workflow.
- Eligibility gate: Check purpose, consent, suppression, operating window, ownership, duplicates, and channel permission.
- Context assembly: Load trusted CRM fields, source data, previous interactions, and the current policy version.
- Engagement: Ask only for missing evidence on the channel the buyer chose or permitted.
- Extraction: Normalize answers into typed values while keeping provenance and uncertainty.
- Decision: Apply hard gates first, then fit and readiness rules. Use a model score only where it has been validated.
- Action: Book, transfer, assign, nurture, close, or suppress through narrow authenticated tools.
- Observation: Record the conversation result, policy version, tool outcomes, human overrides, and downstream sales events.
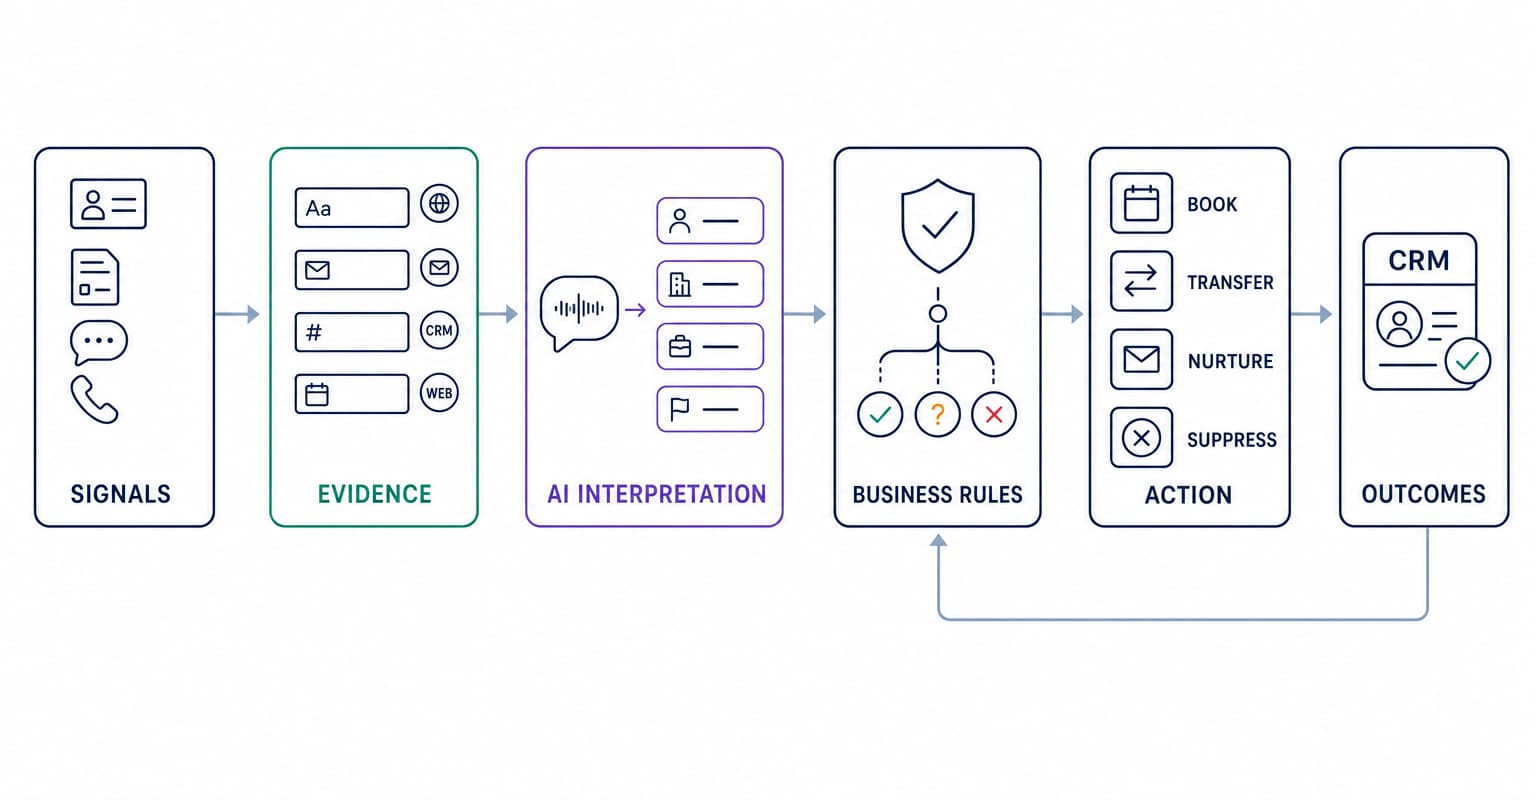
For voice workflows, Dasha can occupy the engagement layer while your application owns eligibility, qualification policy, and CRM truth. Calls can receive lead context, invoke narrow business tools during the conversation, transfer to a person, and return completion or failure events. Structured post-call fields can feed the same decision record as chat, email, or enrichment inputs.
Treat every write-capable tool as a production API. Validate arguments on your server, use least-privilege credentials, and add an idempotency key so a retry cannot create a second meeting or duplicate lead. Define a recovery state for timeouts and partial failure. A well-handled conversation followed by a failed CRM update is still a failed workflow.
Put compliance in the eligibility gate
Consent and suppression rules must execute before engagement, outside the prompt. Store where consent came from, what purpose and channel it covers, when it was captured or revoked, and whether suppression reached every connected system.
For US outbound voice qualification, the FCC's AI voice ruling says current AI-generated voices fall within TCPA restrictions on artificial or prerecorded voices. Covered calls require prior express consent absent an applicable exemption or emergency purpose. The FTC telemarketing guidance separately covers areas such as Do Not Call rights, calling-time restrictions, caller ID, opt-outs, and recordkeeping. The applicable controls depend on the campaign purpose, recipient, destination, and jurisdiction.
Test every layer, then connect it to revenue
Build an evaluation set from real lead patterns with personal data removed. Include clear fits, clear disqualifiers, vague answers, missing fields, contradictions, objections, repeated questions, tool failures, opt-outs, and attempts to make the agent ignore its instructions. For voice, include accents, background noise, interruptions, silence, names, dates, and quantities.
One aggregate “qualification accuracy” number hides where the system fails. Measure each layer:
| Measure | What to calculate | Why it matters |
|---|---|---|
| Field extraction quality | Correct values and correct unknown states, field by field | A strong overall score can hide a weak field that controls routing |
| Decision agreement | False positives and false negatives against a fixed human rubric | The two errors have different commercial costs |
| Action integrity | Correct bookings, transfers, assignments, suppressions, and CRM writes | A correct decision can still produce a broken operation |
| Conversation completion | Completed evidence collection by source and channel | Reveals friction from question order or channel choice |
| Human override rate | Overrides by outcome, reason code, and policy version | Shows where sales does not trust or understand the result |
| Downstream quality | Sales acceptance, held meetings, opportunities, and wins by cohort | Tests whether qualification predicts a useful business outcome |
Choose thresholds based on the cost of each error. A false positive consumes seller time. A false negative can hide a valuable buyer. High-volume transactional sales and low-volume enterprise sales will often make different tradeoffs.
Qualification rate by itself is easy to inflate by lowering the threshold. Meetings booked can rise while no-shows and sales rejection rise with them. Keep the lead source, segment, policy version, and attribution window attached to downstream results.
Start in shadow mode. Let the system create fields and recommendations while people retain the final action. Review high-impact disagreements, fix the schema or policy, then enable one write action at a time. CRM notes are lower risk than booking or live transfer. Suppression must work from the first live interaction.
Common failure modes and their fixes
- One opaque score: Split fit, readiness, and operational status. Store reason codes and evidence.
- Missing data treated as failure: Preserve unknown and ask, nurture, or review according to policy.
- The prompt becomes the policy engine: Move exclusions, thresholds, permissions, and routing into versioned code.
- Stale enrichment drives outreach: Record source and timestamp. Confirm high-impact fields during the conversation.
- The model overqualifies vague answers: Require direct evidence for decisive fields and route inference to clarification.
- No safe human path: Allow transfer, callback, review, and buyer-requested escalation.
- Success equals meetings booked: Track held meetings, accepted leads, opportunities, and human overrides.
- No rollback by version: Log the prompt, model, schema, policy, and integration versions on every result.
What to look for in an AI lead qualification platform
Start from the part of the system you need:
| Primary need | Best-fit product category |
|---|---|
| Research, enrichment, and account ranking | GTM data platform or CRM scoring tool |
| Web, SMS, or messaging conversations | Messaging automation or conversational AI platform |
| Phone conversations, tool calls, and human transfer | Managed production voice AI platform such as Dasha |
| Bespoke logic across several channels | Custom orchestration with specialist channel runtimes |
For any category, evaluate structured outputs, evidence provenance, tool schemas, retries, idempotency, versioning, test support, traceability, handoff options, suppression, event delivery, and data retention. For voice, also evaluate interruption handling, speech recognition under real conditions, response latency, telephony compatibility, transfer behavior, and call inspection.
The best first deployment is narrow: one lead source, one language, a small evidence schema, four to six terminal outcomes, and a human fallback. If phone qualification is the missing layer in your workflow, build the first voice agent with Dasha and test the path from eligibility gate to CRM writeback before increasing traffic.
Take Your Lead Qualification to the Next Level!
Leverage the power of Dasha's AI in your lead qualification process. Boost your efficiency and success rate. Start your free trial now and qualify like a pro!