
An in-car voice assistant has to understand speech through road noise, respond before the exchange feels broken, work through poor connectivity, and keep conversational AI away from unsafe vehicle actions. Those constraints make it a different engineering problem from adding a microphone to a mobile app. Here is the architecture, interaction model, safety boundary, privacy program, and test plan technical teams need to build a production system.
What is an in-car voice assistant?
An in-car voice assistant is a spoken interface for vehicle functions and connected services. A driver can ask it to set a destination, play media, place a call, adjust cabin temperature, read an OEM-grounded explanation of a dashboard warning, or use an external service. The assistant captures speech, interprets the request, decides whether an action is allowed, executes it through a controlled integration, and confirms the result.
Capabilities, benefits, and limitations
The system can combine vehicle control with general assistant behavior, but each capability carries a different integration and safety burden.
| Area | What it can do | Evaluator takeaway |
|---|---|---|
| Core capabilities | Navigation, media, calls, messaging, cabin comfort, vehicle status, owner support, and connected tools | Scope the first release around a small, high-value command catalog |
| Driver benefit | Reduce some screen taps and long menu sequences, support hands-busy interaction, and combine several steps in one request | Measure task time and cognitive demand, not feature count |
| Product benefit | Give an OEM or mobility product a branded interface, expose vehicle features, and update connected services after sale | Separate brand behavior from privileged vehicle control |
| Technical limits | Cabin noise, uncertain endpointing, weak connectivity, stale vehicle state, and dependency latency | Test the complete path in moving vehicles and degraded networks |
| Safety and privacy limits | Voice still creates cognitive load, and cabin audio can include passengers, location, contacts, and sensitive requests | Treat safety, security, privacy, and access control as launch gates |
Embedded assistants versus standard projection
“In-car” describes several architectures with different control boundaries:
| Experience | Primary host | Typical scope | Main tradeoff |
|---|---|---|---|
| OEM-embedded assistant | Vehicle head unit, often with cloud services | Vehicle controls, navigation, media, owner support, and connected data | Deepest integration with the largest release, safety, and lifecycle burden |
| Standard phone projection | Smartphone with a conventional CarPlay or Android Auto interface | Calls, messages, media, navigation, and supported mobile apps | Faster access to a familiar ecosystem, with vehicle functions bounded by the OEM integration |
| Extended projection | Smartphone plus deeper OEM integration, such as CarPlay Ultra | Instrument displays, radio, climate, and supported vehicle-specific functions in addition to phone services | Scope can approach an embedded experience, but support and permissions vary by automaker and vehicle |
| Aftermarket or accessory assistant | Phone or add-on hardware connected to the car | Media, calls, navigation, and smart-home commands | Little native vehicle context or control |
Standard projection should not be treated as a synonym for a fully embedded assistant. It normally centers on phone services. Extended projection can reach climate, radio, displays, and OEM functions when the automaker implements those interfaces. In every case, the vehicle determines the final control boundary.
A fixed command recognizer can map “temperature 70” to one function. A conversational assistant goes further. It can resolve “I’m cold,” remember which seat the speaker occupies, ask a short clarification, and carry context into the next turn. That flexibility increases the need for strict execution policy.
For teams building the connected conversation layer, we provide a managed voice runtime, agent configuration, tools, browser voice testing, call inspection, and monitoring. Our current Dasha documentation covers the application and REST API surface. We do not replace the cabin microphone array, embedded wake-word processor, Android Automotive OS integration, or the engineering controls needed for vehicle actuation. Our platform fits as one managed layer in a complete in-car system.
How an in-car voice assistant works
The spoken exchange is only the visible part. A production request passes through several components:
- Activation: A steering-wheel button, on-screen control, or local wake-word detector opens a session. Push-to-talk is a useful fallback when a hotword fails or the cabin is noisy.
- Audio preparation: The vehicle applies beamforming, acoustic echo cancellation, noise suppression, and voice activity detection. It also identifies the active microphone or seat zone when the hardware supports it.
- Speech recognition: Streaming automatic speech recognition converts audio to partial and final text. Partial results can start intent routing before the user finishes speaking.
- Conversation runtime: A rules engine, large language model (LLM), or both interpret the request using dialogue history, user permissions, vehicle state, and available tools.
- Policy and fulfillment: A typed tool layer validates arguments and decides whether the action is allowed. Approved commands pass to navigation, media, account services, or a vehicle command gateway.
- Speech response: Text-to-speech begins playback. The runtime must keep listening so the driver can interrupt, correct, or cancel the response.
- Observation: Correlated events record activation, recognition, model, tool, command, and speech timing so failures can be reconstructed.
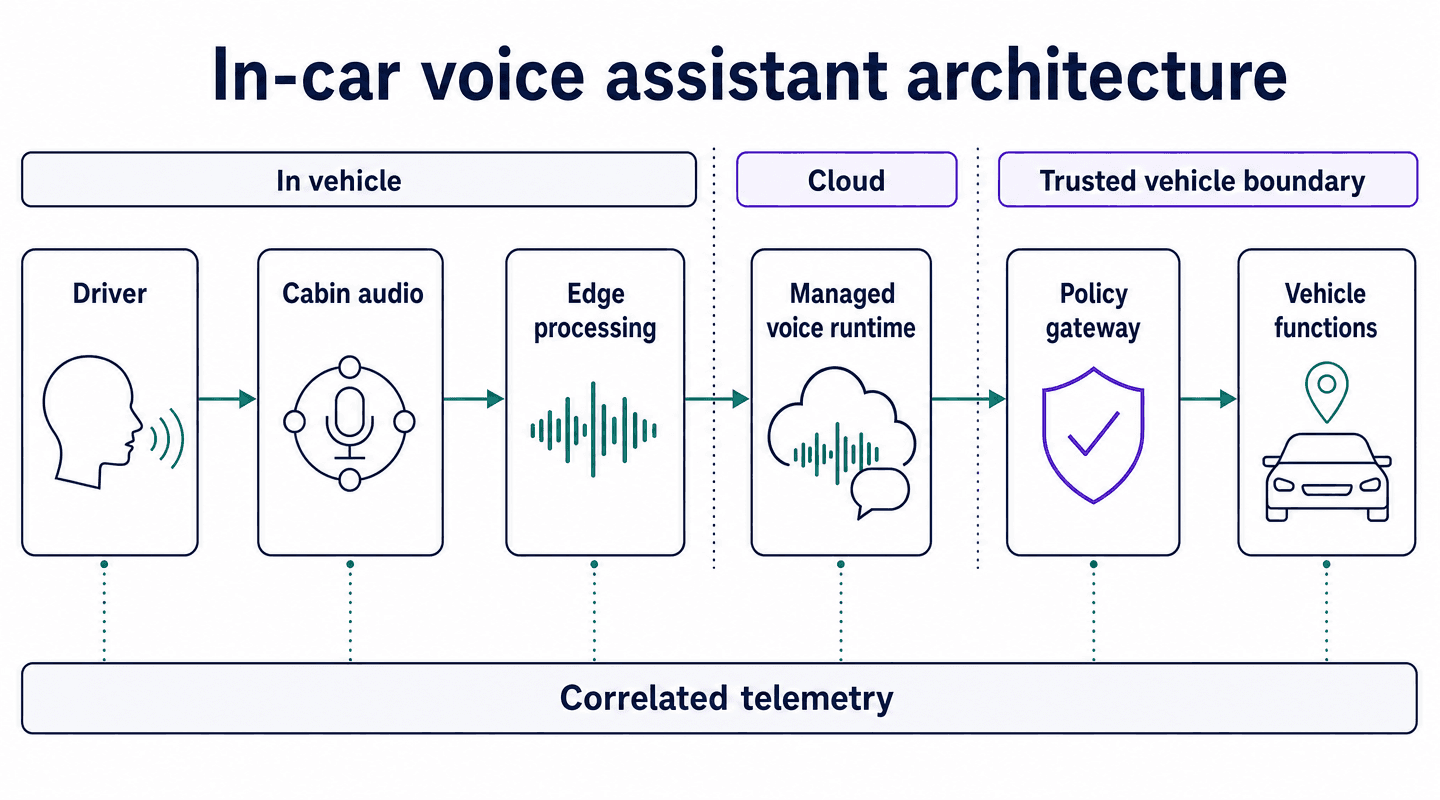
Android Automotive OS exposes a similar separation. Its voice interaction model distinguishes activation, speech recognition, the session that owns interaction logic, and services that fulfill commands. Vehicle controls such as heating, seats, and interior lights use CarPropertyManager and require correctly configured privileged access. The AAOS integration guide is a useful reference even if your head unit uses another operating system.
Use a hybrid edge and cloud design
The edge and cloud solve different problems. A serious design assigns each capability deliberately.
Keep these functions in the vehicle where possible:
- push-to-talk and wake-word detection;
- acoustic echo cancellation, beamforming, and noise reduction;
- a small set of offline commands and cancel behavior;
- seat or speaker-zone detection;
- the command policy gateway and final permission check;
- a safe response when connectivity disappears.
Use the cloud for functions that benefit from larger models and current data:
- open-ended language understanding;
- long-tail questions and owner-manual retrieval;
- connected search, traffic, weather, and commerce;
- account-specific tools and external services;
- fleet-wide model updates, evaluation, and observability.
The offline path should complete a small number of high-value tasks reliably. “Cancel,” “stop,” and basic comfort controls are better candidates than open-ended search. When the network drops, the assistant should state the limitation once, keep local commands available, and avoid pretending a cloud action succeeded.
Optimize the turn the driver hears
Model response time is one part of perceived latency. The useful measure starts when the driver finishes speaking and ends when the first relevant audio response begins. Break that interval into endpointing, final recognition, runtime and model work, tool execution, and speech synthesis. Track median and tail latency for each stage, because one slow tool can make an otherwise fast stack feel unresponsive.
Do not shorten latency by cutting off hesitant speakers. Drivers pause while watching traffic, pronounce unfamiliar place names, and correct themselves mid-sentence. Endpointing has to balance response speed against false end-of-turn decisions. Our voice AI latency guide explains how to measure that tradeoff across the full turn.
Put a hard boundary between language and vehicle control
An LLM should propose a structured action. It should never write directly to a vehicle bus or privileged property API.
Use this execution sequence:
speech intent -> typed action -> schema validation -> driver and vehicle policy -> confirmation when required -> vehicle gateway -> state check -> execution -> result confirmation
The policy layer should evaluate at least:
- driver or passenger identity and seat zone;
- whether the vehicle is parked, moving, or in another relevant state;
- the requested property and allowed value range;
- whether the action is reversible;
- whether explicit confirmation is required;
- the freshest authoritative vehicle state;
- tool timeout, duplicate, and cancellation behavior.
Risk-tier the command catalog before writing prompts:
| Command class | Examples | Recommended handling |
|---|---|---|
| Routine read-only information | Next turn, media status, non-safety owner question | Answer briefly and name uncertainty when data is stale |
| Safety-sensitive vehicle information | Dashboard warnings, tire pressure, driving range | Use OEM-authoritative data and content, expose freshness and provenance, avoid diagnosis, and fall back safely when evidence is missing |
| Reversible comfort action | Temperature, seat heat, media volume | Execute through an allowlisted tool and confirm compactly |
| State-changing connected action | Route change, service booking, food order | Confirm target, price, or destination before committing |
| Safety-related or restricted action | Driver-assistance settings, doors while moving, security functions | Use deterministic policy, state checks, and OEM-approved behavior; deny unsupported requests |
Dashboard warnings, tire pressure, and range need a stricter answer path than general knowledge. Ground the response in the vehicle's authoritative signal and OEM-approved explanation. Include the signal time, source, units, and vehicle context in the tool result. The assistant should describe the observed status and approved next step, without diagnosing a fault or inventing how far the car can travel. If the source is missing, stale, conflicting, or outside its operating range, say that the status is unavailable and use the vehicle program's safe fallback, such as the instrument display, owner guidance, or roadside-support flow.
Prompts can guide wording. They are not an authorization system. The tool must reject unknown fields, out-of-range values, stale state, and calls made with the wrong identity. A valid JSON payload can still represent an unsafe action.
This policy gateway is an architecture pattern. It is not an automotive certification, safety case, or proof of cybersecurity compliance. Each vehicle program and target market still requires its own hazard analysis, threat analysis, access model, degraded-mode behavior, verification, and approval against the requirements that apply there.
Voice does not remove driver distraction
Voice can reduce visual and manual interaction, but hands-free operation still creates cognitive load. More dialogue turns, recognition errors, and long repair loops keep the driver occupied.
An October 2014 University of Utah study for the AAA Foundation found that task duration and interaction errors tracked cognitive demand. Simple vehicle commands such as adjusting climate were relatively light, while composing responses to messages produced much higher demand. The cognitive-distraction findings point to practical design rules:
- keep spoken options to four or five when a menu is unavoidable;
- accept flexible phrasing so drivers do not learn a command syntax;
- prefer one short clarification over a long list of guesses;
- read only the information needed for the immediate decision;
- block or defer high-demand tasks while the vehicle is moving;
- let the driver cancel or interrupt at any point.
The safest response is often a short confirmation such as “Driver temperature set to 70.” Repeating the whole request or explaining internal reasoning adds time without helping the driver.
Design privacy for everyone in the cabin
An in-car assistant can capture more than the account holder's command. Microphones may also pick up passengers, children, phone calls, addresses, health information, payment details, and background conversation. Location, vehicle identifiers, contacts, tool results, and derived preferences can make the session more sensitive than the audio alone.
Build the privacy program around the complete data path, from the wake-word buffer to every model, tool, log, support console, analytics store, and backup.
Give occupants meaningful notice
Use an audible tone and a persistent visual state to show when the assistant is listening, processing, or recording. Make the notice understandable without requiring the occupant to sign in or find a phone setting. Shared, rental, and fleet vehicles need a notice path for passengers who never accepted the driver's account terms.
Define a lawful basis for each processing purpose before launch. Activation, command fulfillment, personalization, product analytics, support review, fraud prevention, and model improvement are separate purposes. A basis that supports fulfilling a requested command does not automatically support indefinite storage or provider training.
Minimize collection and separate purposes
Keep local wake-word detection separate from an active cloud session where the hardware permits it. Do not retain ambient audio simply because the microphone is available. Send only the audio, vehicle properties, location precision, identity, and history needed for the current task.
Classify raw audio, transcripts, vehicle telemetry, precise location, contact data, tool payloads, identifiers, and inferred preferences separately. That makes it possible to set narrower access, retention, and training rules instead of applying one broad policy to every artifact.
Set retention, deletion, and opt-out behavior
Assign a purpose and retention period to each data class. Raw audio may need a different period from a transaction record or an aggregate latency metric. Expiration must cover primary stores, logs, analytics copies, support exports, subprocessors, and the documented backup lifecycle.
Provide controls to delete a profile and its linked history, disable personalization, and opt out of optional recording or secondary model use where applicable. The basic command path should continue without a personal profile when the product and safety design allow it. Deletion needs an auditable workflow and a defined result when a record must be retained for another lawful purpose.
Restrict access and vendor use
Encrypt data in transit and at rest, authenticate every recording or transcript request, enforce least-privilege roles, and log access to sensitive session data. Remove secrets and unnecessary personal data before sending tool results back into the model context.
Map every speech, model, analytics, support, and storage provider. Contracts and technical configuration should state whether each provider may retain content or use it to train models. Do not allow occupant conversations to become general provider-training data unless that use has a valid legal basis, is clearly disclosed, and respects required choices. A provider switch or model upgrade should trigger a new data-flow review.
Treat voice biometrics as a separate system
Ordinary recorded speech is not automatically a biometric identifier. Speaker recognition changes the analysis when the system creates or uses a voiceprint or template to identify a person. Where biometric rules apply, the program may need specific notice or consent, a limited purpose, strict access, a retention and destruction schedule, and a way to use the assistant without biometric identification.
Do not infer that a recognized voice is sufficient authorization for a payment, security, or safety-sensitive action. Identity confidence, account authentication, vehicle state, and action-specific policy still have to agree.
Account for children, passengers, and market variation
The driver's choice does not automatically cover every passenger. Use conservative defaults for unknown occupants, avoid retaining child speech for optional analytics or training, and provide a non-personalized path when the system cannot establish the permissions required for personalization. Products that knowingly collect children's data may face additional parental notice, consent, minimization, and deletion duties.
Privacy, call-recording, biometric, precise-location, child-data, cross-border-transfer, and vehicle-cybersecurity rules vary by jurisdiction and deployment model. Maintain a market-by-market data map with the responsible controller or processor, lawful basis, notices, choices, retention, access, transfers, incident path, and approval owner. Where the GDPR applies, its core principles require a defined purpose, data minimization, and limited retention. Organizations must identify an applicable legal basis before processing personal data, and special categories such as biometric data used to uniquely identify a person generally require a specific exception. Individuals also retain GDPR rights over their personal data.
Using our managed runtime does not transfer these responsibilities to us. The vehicle or service operator remains responsible for its notices, lawful basis, configuration, downstream tools, retention, access, market-specific requirements, and launch approval.
Build the first version around tasks, not personality
A branded voice and tone matter after the assistant completes useful tasks reliably. Start with a narrow task catalog and an explicit contract for every action.
1. Define the operating envelope
Specify vehicles, head-unit platforms, languages, markets, user profiles, connectivity assumptions, and drive states. Decide what works offline and which tasks require an authenticated account.
2. Write task contracts
For each task, record example phrasing, required data, permissions, valid values, confirmation rule, timeout behavior, offline behavior, user-visible result, and audit event. “Set the temperature” is incomplete until the system knows the zone, units, allowed range, and current state.
3. Establish the platform boundary
Choose what the OEM or app team owns and what a provider supplies. The in-vehicle layer usually owns microphones, activation, audio routing, display state, vehicle permissions, and the command gateway. The conversational layer can own streaming dialogue, model orchestration, tools, context, speech output, and telemetry.
With our managed platform, you can prototype and test that conversational layer through browser voice, configure typed business tools, inspect completed sessions, and monitor runtime behavior. The Dasha testing guide documents the current browser, voice, integration, and pre-production workflow, while the Call Inspector exposes completed-session transcripts, audio, model and tool details, events, and component latency. Native head-unit audio and vehicle APIs still need an integration layer owned by your team. This separation also makes it easier to replace speech or model providers without rewriting vehicle control policy.
4. Implement interruption and recovery first
Test cancel, correction, barge-in, silence, and loss of connectivity before adding open-ended conversation. A driver who says “No, the passenger side” should be able to correct a temperature action without restarting. If a tool times out after submitting an order, query the final system state before retrying.
5. Make every action observable
Use one correlation ID across audio/session events, recognition, model calls, tools, vehicle commands, and the final state. A transcript alone cannot show whether the command ran, which zone changed, or why the response arrived late. The broader agent runtime architecture applies here: session state, tool policy, timeouts, and telemetry belong in the execution layer.
6. Release by command and cohort
Start with a parked-mode pilot or a small driver cohort. Enable low-risk commands first. Expand only when task completion, false activations, latency, interruption recovery, and denied-action behavior meet the launch criteria. Keep a known-good configuration and a way to disable the connected assistant without removing basic vehicle controls.
Test in a real cabin, across the full path
A quiet desk test proves very little. Build a matrix that crosses acoustic conditions, network conditions, speakers, tasks, and vehicle state.
| Test dimension | Cases to include |
|---|---|
| Cabin audio | HVAC low and high, music, open windows, rain, highway noise, passenger speech |
| Speaker variation | Accents, speech rate, hesitant speech, children and adults, driver and passenger seats |
| Turn-taking | Long pauses, self-correction, overlapping speech, barge-in during synthesis |
| Connectivity | Offline, high latency, packet loss, network handoff, cloud timeout |
| Vehicle state | Parked, moving, unavailable sensor, stale property, denied permission |
| Tool behavior | Slow response, invalid result, duplicate request, partial success, ambiguous timeout |
| Safety and privacy | False wake, restricted command, wrong profile, recording disabled, data deletion |
Measure outcomes, not only word error rate:
- false wake and missed activation rates;
- first-turn and eventual task completion;
- incorrect action and safe-denial rates;
- end-of-utterance to first-audio latency at median and tail percentiles;
- interruption and correction success;
- tool and vehicle-command success;
- repeat, abandonment, and fallback rates;
- task duration and number of dialogue turns.
Run scripted regression tests for known commands, then add recordings from consented real-world sessions. Segment results by cabin, road, microphone, language, and vehicle software version. Aggregate success can hide a severe failure in one model or seat zone. Our voice agent testing guide covers a broader production test program.
Choosing the right production approach
The right stack depends on how much of the vehicle, operating system, and conversational runtime you own.
| Approach | Best fit | Your team still owns |
|---|---|---|
| Turnkey automotive assistant | OEM or Tier 1 seeking embedded audio, edge speech, head-unit integration, and professional services | Brand behavior, vehicle policy, acceptance, data governance |
| Mobile ecosystem assistant | Product that mainly needs navigation, media, calls, and familiar mobile accounts | Supported app experience and limited vehicle integration |
| Our managed conversational runtime | Technical team that owns the HMI and vehicle gateway but wants managed dialogue execution, tools, testing, and monitoring | Embedded audio, native integration, command policy, safety validation |
| Open-source or custom stack | Research program or platform team with unusual hardware and full infrastructure capacity | Integration, hosting, scaling, observability, updates, and on-call operations |
Evaluate with one end-to-end scenario instead of a vendor feature checklist. Use a noisy-cabin command that needs context, one clarification, a vehicle or connected tool call, interruption, and final confirmation. Then disconnect the network and deny the permission. The test exposes the boundaries between the demo and the system you can operate.
Frequently asked questions
What is the difference between in-car voice control and a voice assistant?
Voice control maps known phrases to predefined commands. A voice assistant can understand varied phrasing, maintain context across turns, combine vehicle data with connected services, ask clarifying questions, and use multiple tools. Both still need deterministic policy for vehicle actions.
Can an in-car voice assistant work offline?
Yes, if the vehicle includes local activation, audio processing, speech or intent recognition, and handlers for an offline command set. Open-ended knowledge, current traffic, account services, and cloud models usually need connectivity. A hybrid design keeps essential local tasks available and degrades connected features clearly.
How is an in-car voice assistant activated?
Common methods are a steering-wheel push-to-talk button, an on-screen tap-to-talk control, and a wake word. Android Automotive OS voice apps must respond to system push-to-talk and tap-to-talk triggers, and they may support hotword activation.
Is an in-car voice assistant safe to use while driving?
Voice can reduce the need to look at and touch a screen. It can still distract the driver, especially when recognition fails, the dialogue runs long, or the task requires composing or comparing information. Safety depends on task design, drive-state restrictions, short interactions, reliable cancel behavior, and validation in real driving conditions.
Can Dasha build a complete in-car voice assistant?
We can provide the managed connected conversation layer, including agent execution, tools, browser voice testing, inspection, and monitoring. A complete automotive product also needs embedded activation and audio processing, native head-unit integration, a permissioned vehicle command gateway, offline behavior, and OEM safety, cybersecurity, and privacy validation.
If you already own those vehicle-side layers, start building with Dasha and evaluate the conversational runtime against your noisiest, highest-value scenario.